Agent Runtime Primitives
Failure Recovery and Retry Contracts in Large-Scale Scheduled Agent Fleets
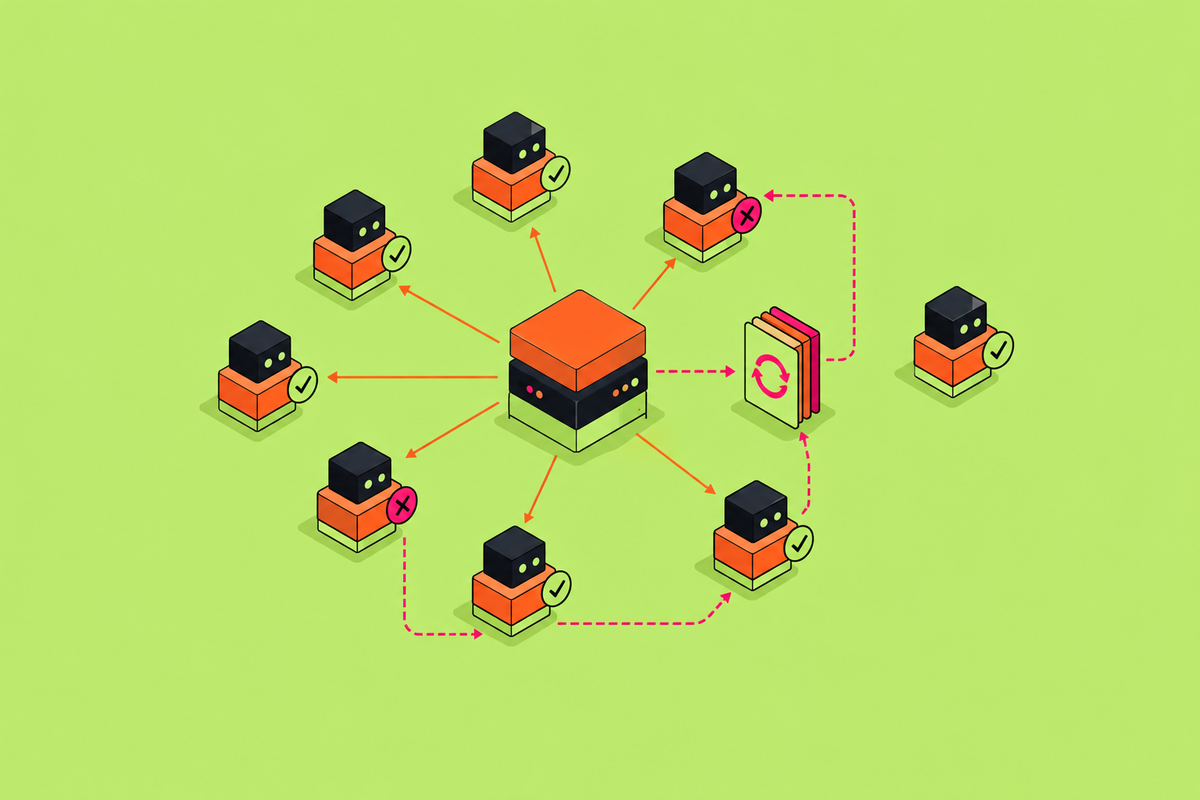
Scheduled agent fleets need four separate recovery contracts, not just retries.
Solenne Kaboré · November 8, 2026 · 9 min read
Section
14 stories in Agent Runtime Primitives
Scheduled agent fleets need four separate recovery contracts, not just retries.
Separate execution, sessions, and memory so agents survive process restarts.
Agents need OS-like runtimes to survive crashes and scale overnight work reliably.
Native state management in agent runtimes solves problems that retrieval benchmarks cannot measure.
Proactive agents need four coordinated primitives to wake with memory.
Agents need one runtime that owns state, memory, and scheduling.
Persistent state and transactional isolation let agent fleets recover reliably from failures.
Agents fail from badly managed context, not small windows.
Well-designed harnesses beat raw model power when managing context across distributed agents.
Why standard containers fail when AI agents write their own code at runtime.
Isolation, state, and scheduling choices decide whether agents survive production.
Choosing agent memory means trading accuracy against latency.
Fixed cloud-era scheduling breaks agent sessions, and runtime adaptation fixes it.
Agents can't safely restart from zero, so preemption needs checkpoints.