First-Class Versus Bolted-On Persistence Signals Every Agent Framework Benchmark Misses
Native state management in agent runtimes solves problems that retrieval benchmarks cannot measure.
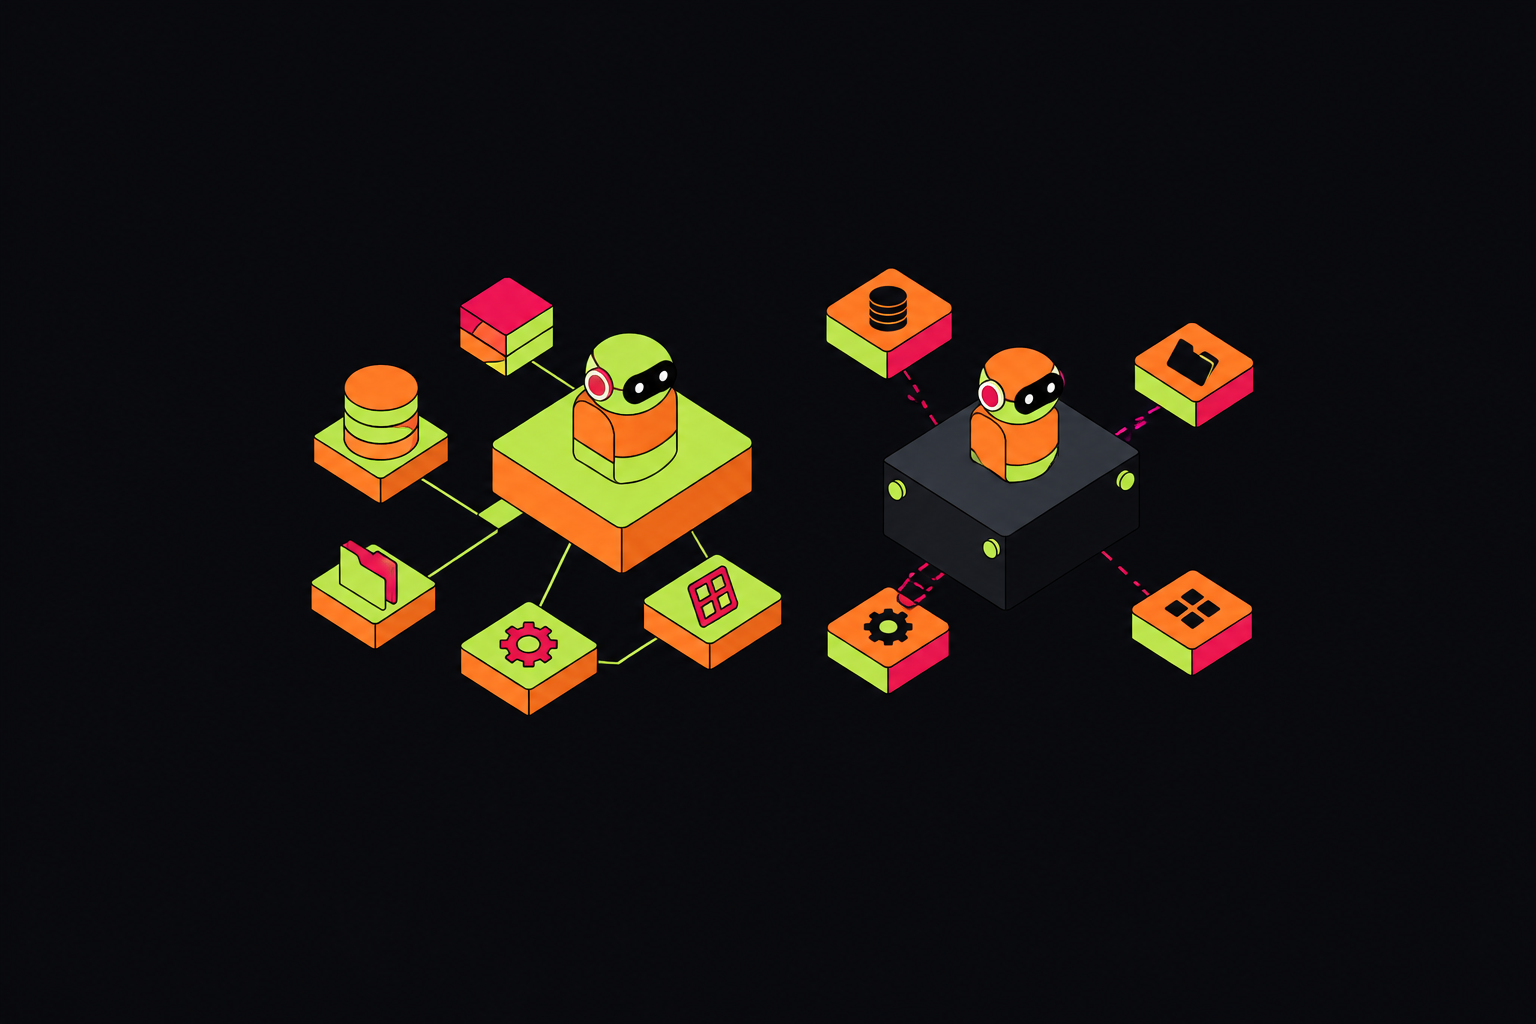
For persistent and scheduled autonomous agents at scale, the key architectural choice is whether the runtime preserves state and supports recovery, or leaves that work to application developers. Recall scores cannot settle that choice.
Why agent benchmarks are built for a world that doesn't exist in production
Recall benchmarks have an obvious appeal because they are reproducible, comparable, and easy to report. The test gives an agent some history, asks a question, and scores its answer. The result looks like a useful measure of memory. But that tightly bounded test leaves out much of what a production agent must do, including deciding when it needs past information and whether that information is still true.
DolphinBench’s authors identify the question itself as a hidden advantage because it signals that retrieval is needed, often pointing toward the fact to retrieve. MOMENTO’s authors describe a similar mismatch between isolated single-session evaluation and deployments where users come back over days and weeks as their goals change. Those users need more than accurate recollection. Their agents must use past actions, preferences, and decisions in work that has consequences, even when the information is spread across separate sessions. Answering a question and completing a task across time are structurally different jobs.
What "persistence" actually means at the architecture level, and why it comes in two incompatible forms
Bolted-on persistence delegates state management to the developer. The framework is stateless by design, and the application adds memory after the runtime has been chosen. First-class persistence assigns that responsibility to the runtime itself, which preserves state, enforces recovery after crashes, and treats durability as a primitive. The distinction is about who owns the contract. Similarly, an operating system can manage process state natively or ask every application to write its own checkpoint logic.
Episodic memory preserves specific past interactions, semantic memory preserves facts and preferences, and procedural memory preserves learned behaviors and rules. These scopes need different persistence contracts because remembering an interaction is not the same as maintaining a current preference or reusing a routine. Bolted-on layers can flatten those differences or serve only one scope. A vector-only store can retrieve semantically similar facts, but similarity alone cannot represent how those facts change over time.
An agent that remembers what happened has not necessarily learned how to do the work again. Reusing a routine requires tracking execution pathways. The runtime’s persistence model therefore limits not only what the agent can recall, but which kinds of continuing work it can support.
Why benchmarks are structurally blind to this divide
A question-answering test can give identical scores to a runtime with native persistence and a stateless framework attached to well-tuned retrieval. Both may return the requested fact correctly. The test never creates a situation in which their different ownership of state becomes visible. Its blindness is built into the format, rather than caused by an unfortunate choice of questions.
DolphinBench pinpoints the shortcut that produces this result. Once the question announces the need for memory, the agent can skip deciding whether to retrieve at all. Recall evaluations consequently give retrieval methods much more room to influence the score than the write strategy beneath them. The test offers few occasions on which writing and updating state determine success.
MOMENTO exposes what changes when sessions depend on one another. Its agents fail primarily by misestimating user state, treating prior history as a reliable substitute for current context even when it may need re-validation. An isolated recall test cannot show when an agent makes that mistake over time. Even a perfectly retrieved statement can be the wrong basis for action now. Published vendor scores add another obstacle when different parties test different platforms with undisclosed configurations, but better reporting alone would not repair this underlying mismatch.
What production failure actually looks like when persistence is bolted on
Stale preference reuse begins with apparently successful memory. The agent retrieves an earlier preference and treats it as current, even though the user’s goals have evolved. MOMENTO identifies this misestimation of user state as the primary failure in its cross-session tasks. Retrieval has worked, yet the task can fail. The missing operation is re-validation, which a system concerned only with saving and finding content does not resolve.
Agents with the same headline gain from retained experience can differ markedly in whether evidence supports the intended save-retrieve-update pathway. A better task score therefore does not prove that the persistence mechanism worked as intended. The benchmark examines memory, procedural reuse, information gathering, and update, with the last dimension testing replacement of outdated state. That replacement is central to the architectural divide because preserving yesterday’s answer is not enough.
Without first-class state management, context that builds up can make an agent stop getting work done altogether, as well as make its answers worse over time. In enterprise settings, the consequences extend beyond the conversation. An agent that skips a procedural step or acts on stale state can change real systems and create cleanup work. These failures may look like poor reasoning in a post-mortem, although the underlying problem is how state was maintained.
The strongest objection — simple retrieval often beats elaborate persistence, so does architecture matter?
Retrieval over raw history and full-context approaches often do as well as more complex memory systems on recall tests, and the comparisons also include BM25. In the comparisons described here, the choice of retrieval method changes accuracy by roughly 20 points, while the choice of write strategy changes it by 3–8 points. BM25 is the weakest retrieval method tested, however.
An agent given exactly the memory it needs can make effectively zero memory calls across many turns, so a reported gain may come from supplied context. Why invest in a more involved architecture if simpler retrieval already produces the answer? Within the boundaries of static recall, that is a reasonable question. Complexity needs evidence.
A retrieval method can find an old preference without establishing whether the preference should still govern an action. DolphinBench’s 2026 results show that even its highest-scoring agent leaves a substantial share of tasks incomplete, while the most expensive agent is neither the most accurate nor the fastest. Those findings show why recall performance alone cannot establish suitability for continuing work, where state changes, task completion, cost, and latency all enter the decision.
What an honest benchmark for agent persistence would actually measure
DolphinBench moves evaluation from remembered answers to completed actions. It requires tests to be solvable with perfect memory and unsolvable without it, so success depends on access to the relevant history. If an agent could complete the task without remembering anything, its success would say little about the memory system. The benchmark also requires cost and latency reporting alongside accuracy.
MOMENTO adds evolving goals and temporal dependencies across sessions. Under that design, earlier context becomes an input to a later decision. The agent must judge its continuing relevance. This is the environment in which stale-state errors become visible, because a fact can be accurately remembered and still need re-validation before use.
PAST-Bench adds mechanism attribution by checking whether gains come from the intended save-retrieve-update pathway. Its results vary across procedural and update abilities, which shows why task scores need that evidence behind them. DolphinBench makes it easier to compare how agents perform in use by requiring total cost and median task latency along with accuracy. Re-reading an entire history for each query can buy a good recall score while hiding an unsustainable production approach. Together, these designs move the field toward evaluating what memory enables, how it enables it, and what the resulting work costs, although they do not by themselves certify the runtime’s architecture.
Persistence as a security surface, not just a reliability feature
Persistent memory also changes how an attack can unfold. A prompt injection confined to a session ends with that session, while memory poisoning can plant an instruction that takes effect during a later, unrelated interaction. The attack and its consequence are separated in time. A layer that preserves content without native governance can therefore preserve hostile instructions as readily as useful experience.
OWASP’s Top 10 for Agentic Applications 2026 names “Memory & Context Poisoning” as a distinct entry. The distinction concerns persistent state rather than only the model’s immediate input and output. Research spanning Northeastern, Harvard, MIT, Stanford, and CMU documented a compromised agent sharing its externally editable “constitution,” a behavioral rule document, with other agents in its network. Reusable procedural rules make this especially relevant to systems meant to learn how to act.
Architectural evaluation must establish whether the runtime can govern that retained state and roll it back to a known-good version. Native rollback requires the runtime to version and manage memory. First-class persistence enables that defense without making each application own it. Durable storage carries no automatic security guarantee, but first-class persistence makes governance and recovery part of the infrastructure contract.
How should builders evaluate infrastructure for hundreds of long-running agents?
Engineers choosing infrastructure should begin with responsibility. Does the runtime preserve state and enforce recovery after crashes, or does the application have to implement those guarantees? For agents that wake on a schedule and resume past work, a recall score does not answer that question. The benchmark findings here also give no basis for ranking vendors on a shortlist. They support a set of tests for whether a platform’s persistence contract fits the work.
The first test should distinguish memory scopes. Does the infrastructure handle episodic, semantic, and procedural memory with distinct contracts, or flatten everything into a vector store? The next test should check whether the agent can replace outdated state as well as retrieve accurate facts. A cross-session test with evolving goals should then examine whether the agent re-validates history before acting, rather than rewarding it simply for finding an earlier statement.
Tests of agents in use should require accuracy, total cost, and median task latency together. Otherwise, a score can hide the cost of reading the whole history again and again, which will not be sustainable in production. Recovery deserves an equally direct question. Can the runtime roll memory back to a known-good state after corruption or poisoning, or must the team build that capability itself? For persistent, scheduled autonomous work, the infrastructure decision is whether durability and governance are native responsibilities of the runtime or unfinished responsibilities handed to the application.
Sources
- PAST-Bench: Benchmarking the Foundations of Recursive Self-Improvement in Personal Agents
- DolphinBench: Mapping the Pareto Frontier of Agent Memory
- Momento: Evaluating Persistent Memory and Reasoning with Multi-Session Agentic Conversations
- The Hidden Footprint: Making Storage a First-Class Metric for LLM Agent Evaluation
- Always-OnAgents:A Survey of Persistent Memory, State, and Governance in LLMAgents